Big Data & Analytics
Data pipelines and dashboards that turn scattered data into decisions your team can actually act on.
Overview
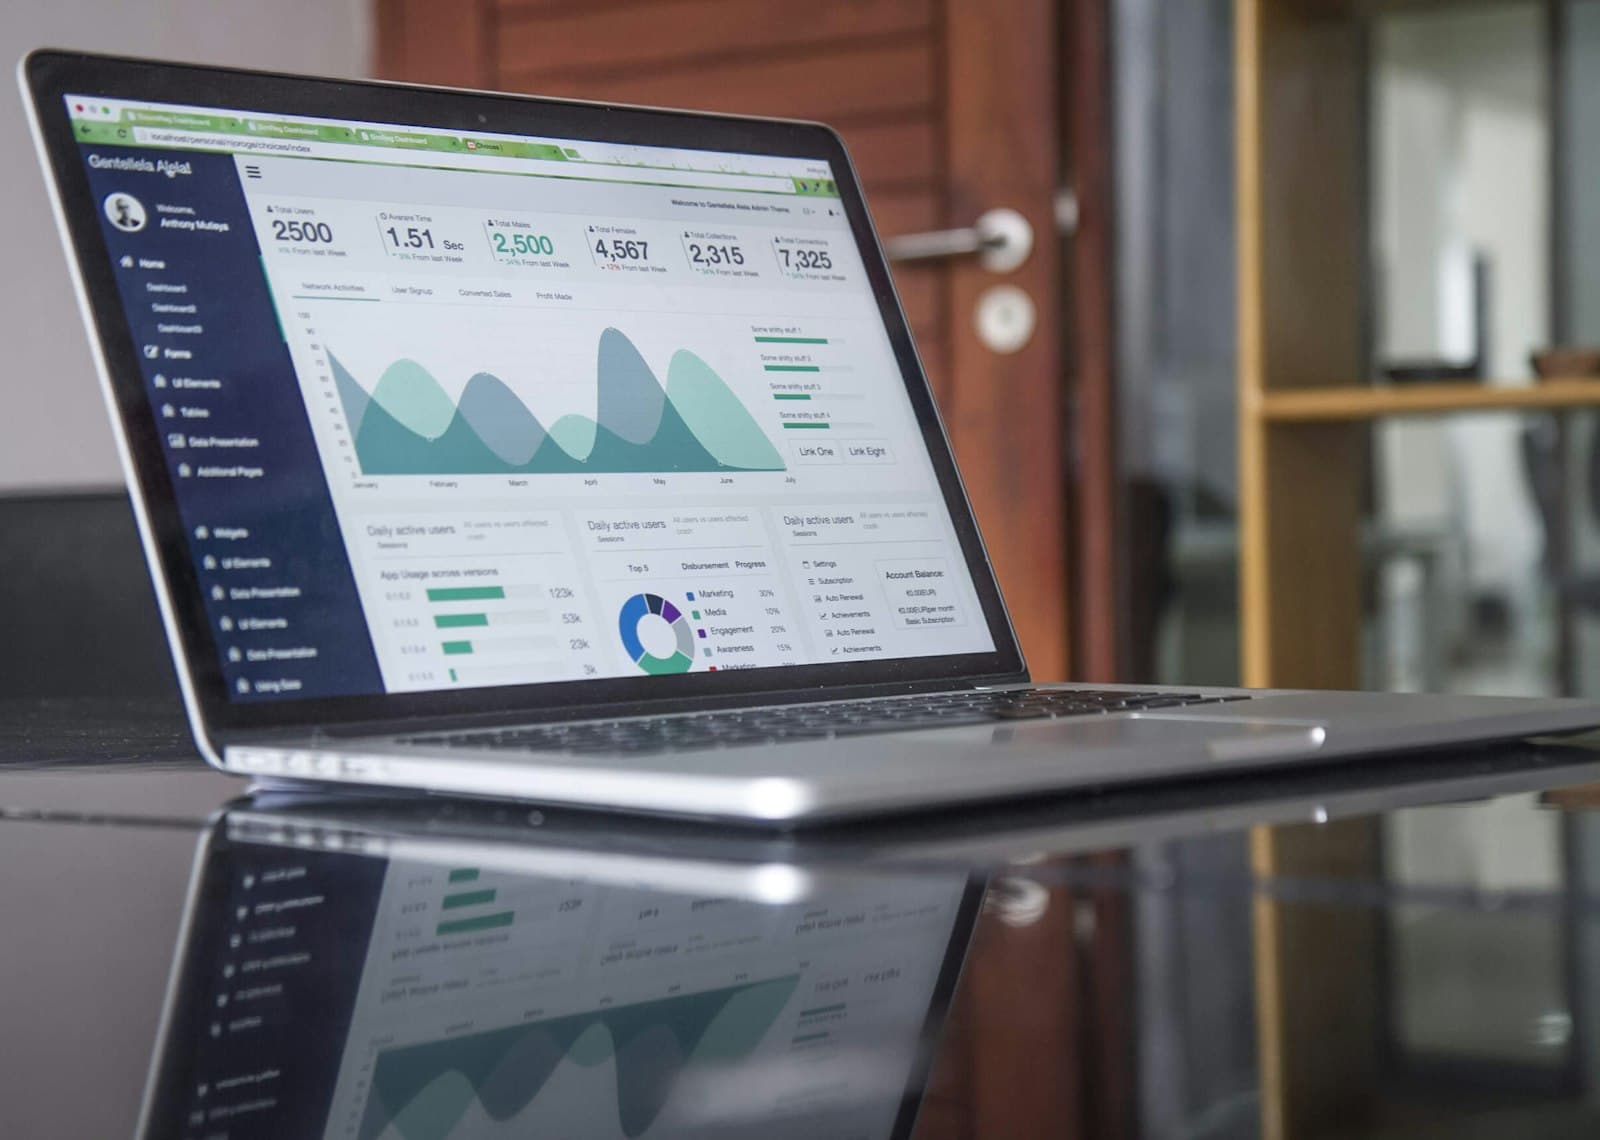
Most organizations don't have a shortage of data — they have a shortage of data they can trust and act on quickly. We build the pipelines that pull data from wherever it lives, clean and structure it reliably, and the dashboards and reporting layers that put it in front of the people who need to make decisions with it.
That includes designing the underlying warehouse or data lake architecture to handle your actual data volume and query patterns, not just today's needs but where the business is headed. For time-sensitive use cases, we build real-time or near-real-time pipelines rather than batch processes that leave decision-makers working from yesterday's numbers.
We also treat data governance as part of the deliverable, not an afterthought — access controls, data lineage, and consistent definitions across teams, so the numbers different departments look at actually agree with each other.
Discover
Understand your business, workflows, and goals before writing a single spec.
Plan
Map requirements, architecture, and a realistic delivery timeline.
Design
Wireframe and prototype the experience your team and customers will use.
Develop
Build in short, reviewable iterations with working software early.
Test
Verify functionality, performance, and security before anything ships.
Launch
Deploy to production with a rollout plan and a rollback safety net.
How we work
A clear, collaborative process from first conversation to long-term support.
Discover
Understand your business, workflows, and goals before writing a single spec.
Plan
Map requirements, architecture, and a realistic delivery timeline.
Design
Wireframe and prototype the experience your team and customers will use.
Develop
Build in short, reviewable iterations with working software early.
Test
Verify functionality, performance, and security before anything ships.
Launch
Deploy to production with a rollout plan and a rollback safety net.
Support
Maintain, monitor, and extend the system as your business grows.
Technologies we use
We pick the right tool for the job, not the other way around.
Python
Our default language for data and ML work, backed by a mature ecosystem of scientific and AI libraries.
Apache Spark
A distributed processing engine we use to transform and analyze data at a scale single machines can't handle.
Kafka
A streaming platform that moves high-volume event data reliably between systems in real time.
PostgreSQL
A reliable, feature-rich relational database we reach for when data integrity and complex queries matter most.
MongoDB
A flexible document database that fits fast-moving products and data shapes that don't map cleanly to strict tables.
AWS
A cloud platform we use for hosting, storage, and managed services that scale with traffic without over-provisioning.
Docker
Containerization that keeps environments consistent from a developer's laptop through staging and production.
Node.js
An event-driven JavaScript runtime that handles concurrent I/O efficiently, giving us fast, scalable APIs and services.
Redis
An in-memory data store we use for caching, sessions, and queues where sub-millisecond response times matter.
REST API
A predictable, well-understood API convention that keeps integrations simple for clients and third-party teams.
Frequently asked questions
In most cases, yes — we integrate with existing BI tools, databases, and cloud data platforms rather than requiring you to replace what already works, unless there's a clear reason to change.
We architect pipelines and storage specifically for your volume and growth trajectory, using distributed processing and appropriately partitioned storage rather than a one-size-fits-all approach.
Where the use case calls for it, yes — we build streaming pipelines for time-sensitive metrics. For less time-critical reporting, scheduled batch updates are often more cost-effective, and we'll recommend accordingly.
Through role-based access on the data layer, documented data lineage, and consistent metric definitions across dashboards, so teams aren't working from conflicting versions of the same numbers.